
Python Instagram and TikTok Downloader API
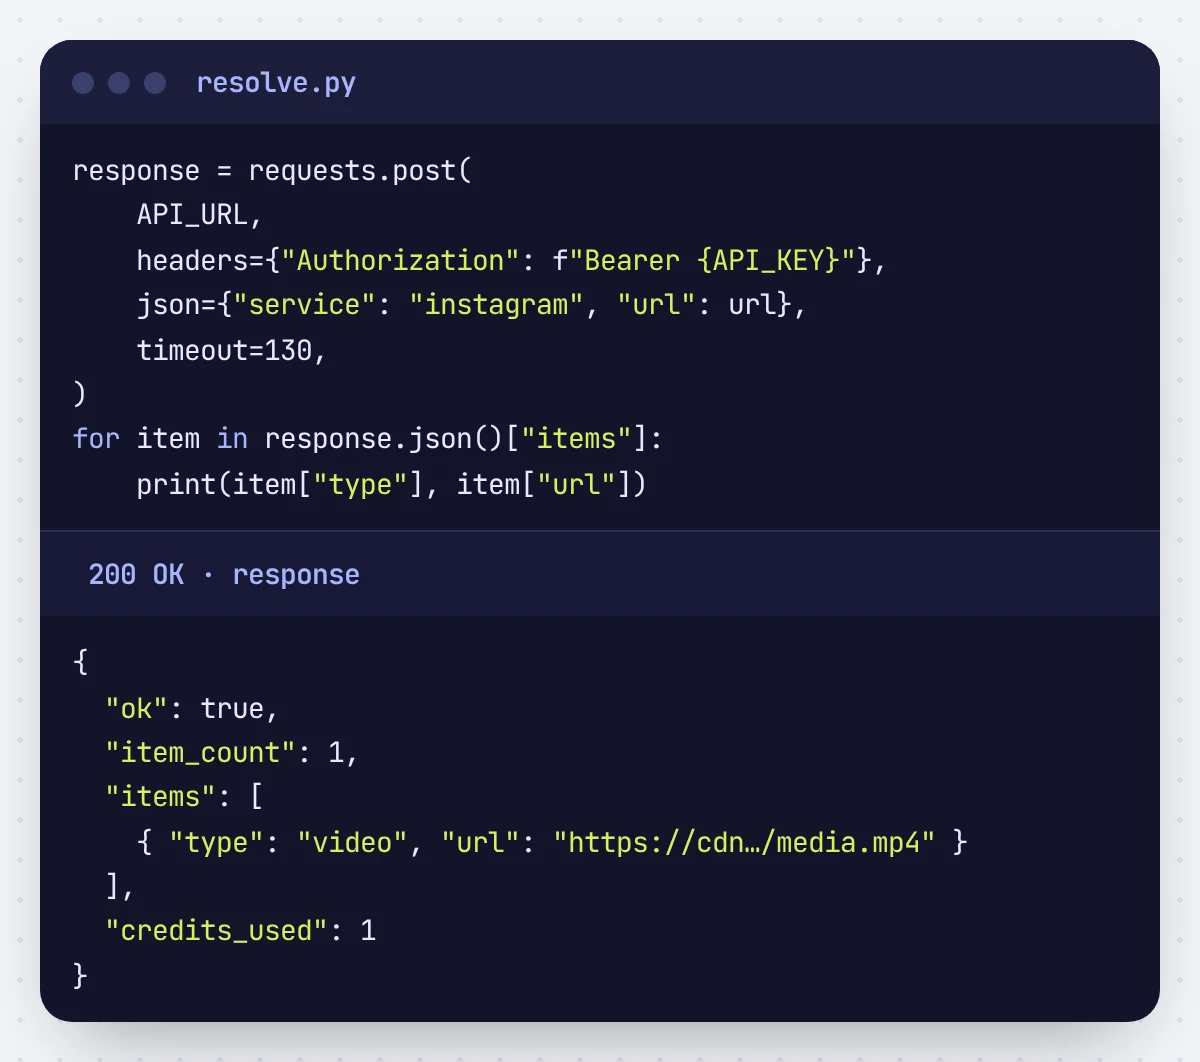
To download Instagram or TikTok media in Python, send the public link to POST https://developers.getinsaver.com/v1/resolve with the requests library. The API answers with direct video and image URLs, and you save them with a streamed GET. No Instagram login, cookies or headless browser runs on your side.
Key facts
- Endpoint
- POST /v1/resolve (one endpoint for every service)
- Free trial
- 20 result credits after email verification, no card
- Price
- from $19 for 7,500 results ($1.33–$2.53 per 1,000)
- Billing
- prepaid credits, no subscription, no expiry; failed or empty requests cost 0
- Credits per result
- 1 (Instagram, TikTok, X, Pinterest) or 2 (Stories, Highlights, Telegram)
- Limits
- up to 20 items per request; 120 requests per minute per account; 2 in progress at once on the trial, 8 on paid accounts
Steps
- Create a free account and verify your email. You get 20 free credits, no card needed.
- Create an API key in Dashboard → API keys and store it as the environment variable
GIS_KEYon your server. - Install the one dependency:
pip install requests. - Save the script below as
resolve.pyand runpython resolve.py.
Complete Python example
It resolves one Reel, retries on rate limits and temporary failures, and saves every returned file under downloads/. Change the service ID and link for TikTok, X, Pinterest, Stories or Highlights.
# pip install requests
import mimetypes, os, time
import requests
API_URL = "https://developers.getinsaver.com/v1/resolve"
API_KEY = os.environ["GIS_KEY"] # keep the key on your server, never in a browser
def resolve(service, url, max_results=10, retries=3):
"""Turn a public link into media items: [{"type": "video", "url": ...}]."""
for attempt in range(retries + 1):
response = requests.post(
API_URL,
headers={"Authorization": f"Bearer {API_KEY}"},
json={"service": service, "url": url, "max_results": max_results},
timeout=130,
)
data = response.json()
if response.ok:
return data
# 429 = rate or concurrency limit, 502/504 = platform hiccup; none of them is charged
if response.status_code in (429, 502, 504) and attempt < retries:
time.sleep(int(response.headers.get("Retry-After", 5)))
continue
raise RuntimeError(f"{data['code']}: {data['message']}")
def download(item, name, folder="downloads"):
"""Media URLs expire within minutes to hours, so save the file right away."""
os.makedirs(folder, exist_ok=True)
with requests.get(item["url"], stream=True, timeout=120) as media:
media.raise_for_status()
kind = media.headers.get("Content-Type", "").split(";")[0]
path = os.path.join(folder, name + (mimetypes.guess_extension(kind) or ".bin"))
with open(path, "wb") as f:
for chunk in media.iter_content(chunk_size=65536):
f.write(chunk)
return path
if __name__ == "__main__":
# TikTok works the same way: resolve("tiktok", "https://www.tiktok.com/@user/video/123...")
result = resolve("instagram", "https://www.instagram.com/reel/SHORTCODE/")
print(f"{result['item_count']} items, {result['credits_used']} credits")
for i, item in enumerate(result["items"]):
print(item["type"], download(item, f"{result['request_id']}-{i}"))
What the API returns
{
  "ok": true,
  "service": "instagram",
  "source_url": "https://www.instagram.com/reel/SHORTCODE/",
  "item_count": 1,
  "items": [
    {
      "type": "video",
      "url": "https://cdn.example/media.mp4"
    }
  ],
  "metadata": {
    "title": null,
    "author": "creator",
    "caption": null
  },
  "request_id": "39a3bff5-0000-4000-8000-000000000000",
  "credits_used": 1
}
A carousel returns one item per slide, up to max_results (1 to 20). credits_used is what the call cost; 1 credit per Instagram post item, 2 per Story or Highlight item.
Service IDs for other platforms
| service | Covers | Credits / result | Link format |
|---|---|---|---|
| Instagram Posts & Reels | 1 | instagram.com/p/... | |
| instagram-story | Instagram Stories | 2 | instagram.com/stories/username/... |
| instagram-highlight | Instagram Highlights | 2 | instagram.com/stories/highlights/... |
| tiktok | TikTok | 1 | tiktok.com/@user/video/... |
| x | X / Twitter | 1 | x.com/user/status/... |
| 1 | pinterest.com/pin/... | ||
| telegram | Telegram Public Media | 2 | t.me/channel/123 |
Errors to handle
| HTTP | Code | What to do |
|---|---|---|
| 402 | INSUFFICIENT_CREDITS | Top up, or lower max_results: a request reserves max_results × credits per result first. |
| 422 | UPSTREAM_REJECTED | The post is private, deleted, expired or login-only. Show the message to your user; nothing was charged. |
| 429 | RATE_LIMITED / CONCURRENCY_LIMIT | Wait for Retry-After seconds and retry. 120 requests per minute per account; 2 at once on the trial, 8 after buying credits. |
| 502 / 504 | UPSTREAM_* | Temporary platform failure. Safe to retry; nothing was charged. |
Every error body is JSON with a stable code and a readable message. The full list is in the API reference.
Coming from Instaloader?
Instaloader's own documentation marks --stories and --highlights as "Requires login", so your Instagram account is in the loop. With this API the function above is the whole integration and no account of yours is involved. See the Instaloader alternative page for a side-by-side comparison.
FAQ
Do I need an Instagram account or cookies?
No. The API reads publicly visible content. Your code sends a link and your API key, nothing else.
Does it work with asyncio or httpx?
Yes. It is a plain HTTPS POST with a JSON body; any HTTP client works. Keep a timeout of at least 130 seconds, because slow platforms can take up to two minutes.
Can I download a whole profile?
No. The API resolves one post, Reel, Story set, Highlight, TikTok, X post, Pin or Telegram post per request. It does not list profiles or return follower data.
Do failed requests cost credits?
No. Credits are reserved while a request runs and refunded in full when it fails or finds no media. You only pay for items that come back.
Related guides
Updated 2026-10-30. The code on this page is executed by our test suite against the API server before every release.